- ES Español (Latinoamérica)

- EN English

3.65. AI265 Reinforcement Learning (Elective)
- Credits: 4
- Hour of this course: Theory: 2 hours; Laboratory: 4 hours;
- Syllabus:
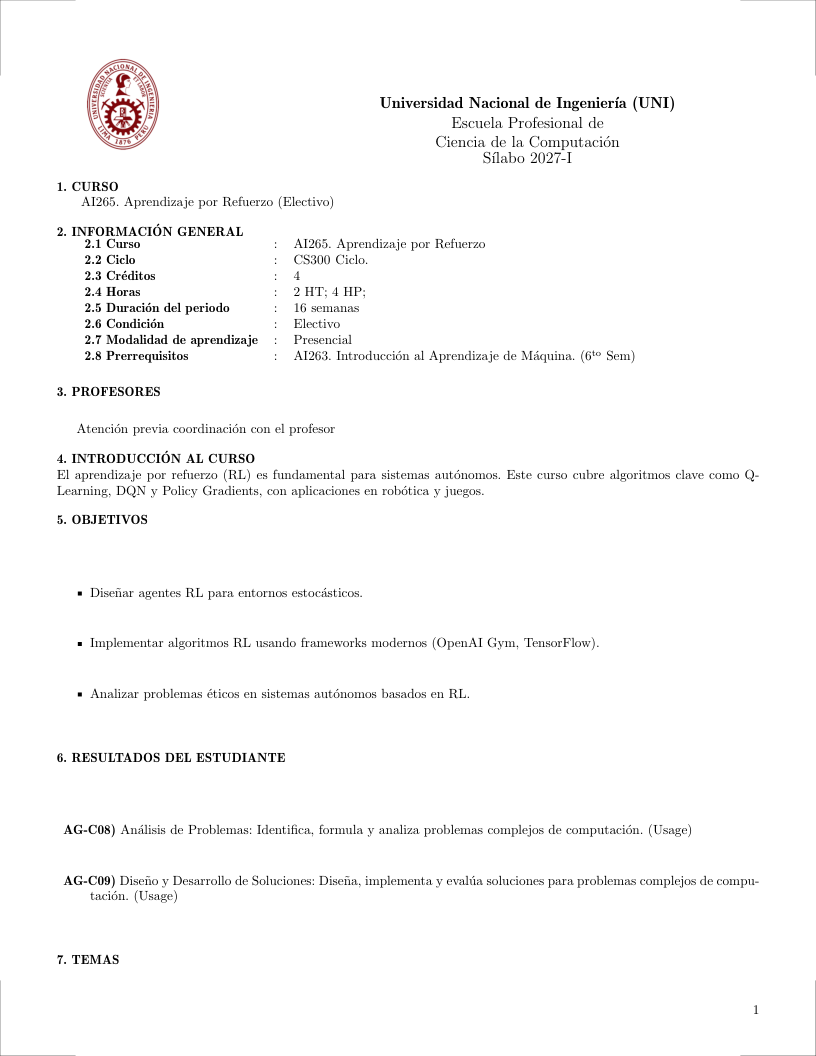
 Español (Latinoamérica)
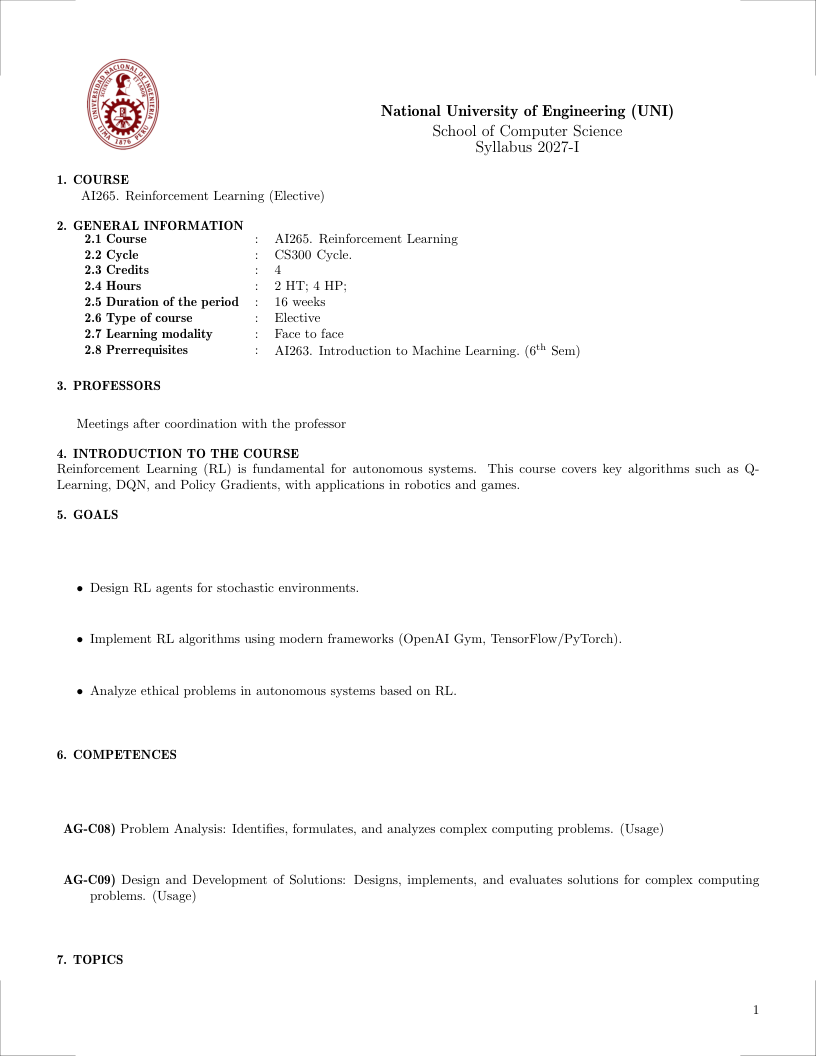 English
- Prerrequisites:
- AI263 Introduction to Machine Learning (6th Sem)
- ES Español (Latinoamérica)
- EN English
3.65.1. Justification Back to top
Reinforcement Learning (RL) is fundamental for autonomous systems. This course covers key algorithms such as Q-Learning, DQN, and Policy Gradients, with applications in robotics and games.
- ES Español (Latinoamérica)
- EN English
3.65.2. Generales Goals Back to top
- Design RL agents for stochastic environments.
- Implement RL algorithms using modern frameworks (OpenAI Gym, TensorFlow/PyTorch).
- Analyze ethical problems in autonomous systems based on RL.
- ES Español (Latinoamérica)
- EN English
3.65.3. Contribution to Outcomes Back to top
- AG-C08) Problem Analysis: Identifies, formulates, and analyzes complex computing problems. (Usage)
- AG-C09) Design and Development of Solutions: Designs, implements, and evaluates solutions for complex computing problems. (Usage)
- ES Español (Latinoamérica)
- EN English
3.65.4. Content Back to top
- ES Español (Latinoamérica)
- EN English
3.65.4.1. Foundations of RL (18 hours) [Skills AG-C08,AG-C09] Back to top
Bibliography: (Sutton and Barto, 2018a)
Topics
- Introduction to the Reinforcement Learning paradigm: agent, environment, actions, states, rewards.
- Formalization of sequential problems: Markov Decision Processes (MDPs) and Partially Observable MDPs (POMDPs).
- Concept of horizon and discount factor (gamma).
- The Bellman Equation: foundation of optimality for state-value (V) and action-value (Q) functions.
- Dynamic Programming Methods: Iterative Policy Evaluation and Improvement.
- Monte Carlo Methods: learning from complete episodes.
- Temporal Difference (TD) Algorithms: TD(0), SARSA, and the bias-variance trade-off.
- Q-Learning (off-policy): derivation, convergence properties, and parameters (learning rate, epsilon-greedy).
Learning Outcomes
- Model problems as MDPs [Assessment]
- Implement Q-Learning [Usage]
- ES Español (Latinoamérica)
- EN English
3.65.4.2. Advanced Classical RL Methods (14 hours) [Skills AG-C08,AG-C09] Back to top
Bibliography: (Sutton and Barto, 2018a)
Topics
- Limitations of tabular methods and the curse of dimensionality.
- Value Function Approximation: replacing tables with parametric models (linear, non-linear).
- Temporal Difference Gradient Algorithms: minimization of the Bellman error.
- Eligibility Traces: unification of Monte Carlo and TD (TD(\(\delta\))).
- Integrated Planning and Learning: Environment models and Dyna-Q algorithms.
- Policy-Based Methods (Policy Search): introduction to policy gradient.
- Exploration vs. Exploitation Trade-off: advanced strategies (UCB, entropy-based exploration).
Learning Outcomes
- Model problems as MDPs [Assessment]
- Implement Q-Learning [Usage]
- ES Español (Latinoamérica)
- EN English
3.65.4.3. Deep Reinforcement Learning (20 hours) [Skills AG-C08,AG-C09] Back to top
Bibliography: (Mnih et al., 2015; Silver et al., 2017)
Topics
- The Deep Learning revolution in RL: training stabilization.
- Deep Q-Networks (DQN): architecture, loss function, and stabilization mechanisms (Target Network, Experience Replay).
- DQN extensions: Double DQN, Dueling DQN, Prioritized Experience Replay.
- Stochastic Policy for continuous action spaces: introduction to Actor-Critic methods.
- Actor-Critic Methods: policy gradient decomposition, advantage function (A2C).
- Advanced Actor-Critic Methods: A3C (Asynchronous Advantage Actor-Critic) and its parallel architecture.
- Direct Policy Gradient: REINFORCE with and without baseline.
- Introduction to maximum entropy methods (Soft Actor-Critic - SAC) and offline RL.
Learning Outcomes
- Train DQN agents in complex environments [Assessment]
- Optimize policies with A3C [Usage]
- ES Español (Latinoamérica)
- EN English
3.65.4.4. Ethics, Safety, and Applications in RL (12 hours) [Skills AG-C08,AG-C09] Back to top
Bibliography: (Sutton and Barto, 2018a)
Topics
- Biases in reward function design: misspecification, misaligned rewards, and reward hacking.
- Challenges of generalization and robustness in RL-trained agents.
- Safety in autonomous systems: avoiding catastrophic failures, Safe RL, and AI Alignment.
- Case studies: analysis of failures in simulations and real-world robots.
- Adversarial attacks on RL: attacks on sensors, policy function, and agent's reward function.
- Social implications: automation, decision-making, and transparency (interpretable agents).
- Ethical frameworks for the development and deployment of autonomous agents.
Learning Outcomes
- Identify ethical risks in RL applications [Familiarity]
- Propose mitigation strategies [Usage]
- ES Español (Latinoamérica)
- EN English
3.65.5. Bibliography Back to top
Sutton, R. and Barto, A. (2018a). Reinforcement Learning: An Introduction. MIT Press.
Mnih, V., Kavukcuoglu, K., Silver, D., Rusu, A., Veness, J., Bellemare, M., Graves, A., Riedmiller, M., Fidjeland, A., Ostrovski, G., Petersen, S., Beattie, C., Sadik, A., Antonoglou, I., King, H., Kumaran, D., Wierstra, D., Legg, S., and Hassabis, D. (2015). Human-level control through deep reinforcement learning. Nature, 518:529–533.
Silver, D., Schrittwieser, J., Simonyan, K., Antonoglou, I., Huang, A., Guez, A., Hubert, T., Baker, L., Lai, M., Bolton, A., et al. (2017). Mastering the game of go without human knowledge. Nature, 550:354–359.